
As you know, Apple released the macOS 26.2 update last week. Among the innovations that came in this update was RDMA networking support over the Thunderbolt 5 port. So what is this RDMA networking?
RDMA is a technology that is the abbreviation of the words Remote Direct Memory Access. By setting up an RDMA network, it’s possible to jointly use the memory of computers connected to each other.
By connecting more than one Mac to each other in cluster mode, you can jointly use the shared memory of Apple Silicon. For example, by connecting 4 of the Mac Studio M3 Ultra to each other, you can obtain 2TB (in words, two terabytes) of unified memory.
Let’s not ruin our morale by talking about the amounts you need to pay and the kidneys we need to sell to be able to do this; let’s proceed by focusing on the technical topics.
This is not Apple’s first acquaintance with cluster structures either. A server service called xGrid, offered in the xServe and MacOS X Server days, gave us the ability to put more than one device to the same work at the same time. This structure was present as a client on MacOS devices of that period, and these clients on the devices could be activated via a MacOS X Server. In the early 2010s, when Apple began to discontinue its server-based products, xGrid got its share of this too.
If you want to learn about the server systems Apple has produced to date, this article may also interest you.
Why Would We Need This?
As you’re aware, the use of artificial intelligence has entered every area of our lives. When you open ChatGPT or Copilot on your computer and type “There’s chicken thigh in the freezer. Can you give me 3 recipes to make with this?”, this query is sent directly to OpenAI‘s or Microsoft‘s data centers and answered there. The MacBook Pro or iPhone you use for the queries you make in AI tools actually functions as a dummy terminal. The queries you make do not use your computer’s system resources.
But along with this, if you want, you can download the LLMs published by OpenAI or DeepSeek to your own computer and run them locally via an application like LM Studio. Why would you want to do this? There are a few different reasons. First of all, security. If you upload a contract about your company to an AI tool and ask it to analyze it, at the simplest you’ll have shared the terms of that contract with the rest of the world. Or the moment you ask AI for support to debug a piece of code you carefully wrote, that code, which is unique to you, becomes part of the world’s common heritage.
Another factor that may motivate you to run an LLM locally can be cost. If you don’t need to use a multimodal AI tool that much, you don’t need to pay for ChatGPT‘s monthly $20 subscription, for example. Of course, the matter is not just paying $20 a month, but the additional Token costs that vary depending on your usage. And this part can hurt a bit.
When you want to run an LLM locally, your computer is no longer a dummy terminal and its own processing power begins to be used. Of course, since your veteran MacBook Air sitting in front of you cannot compete in processing power with OpenAI‘s trillion-dollar data centers, you may get slightly slower answers when you make overly complex requests.
When it comes to the speeds of AI tools, the unit of measure to be considered is Tokens/Second. Every query you write and every answer you get is evaluated according to this unit of measure. If you use ChatGPT for free, the reason it says “We also have subscription packages, wouldn’t you like one?” after a certain amount of usage is this. Free accounts have a certain daily Token limit and won’t let you do operations above this.
If you like, let’s return to the topic of running an LLM locally. Along with the requirement to run LLMs locally, using computers in cluster mode also became popular again. Let there not be a misunderstanding here. I’m not talking about server cluster structures. That’s already in use at all times anyway. But I mean small workgroups combining the power of their personal computers or workstation computers and using them in the mode of mini supercomputers. The basic motivation for creating a cluster using computers is also to obtain higher processing speed. While an M4-processor MacBook Pro you use can process data at a speed of, for example, 5 Tokens per second for a single query on its own, a cluster created by bringing several computers together can process, for example, 25 Tokens. And this means you can get faster responses to your queries.
What Do We Need for This?
Mac
RDMA over Thunderbolt requires that the computers you’ll use each have a Thunderbolt 5 port. Therefore, your first need is a few Macs with Thunderbolt 5 support that can form a cluster. As of December 2025, when this article was written, only the following computers within Apple’s product range have a Thunderbolt 5 port.
- MacBook Pros with M4 Pro and M4 Max processors
- Mac mini with M4 Pro processor (attention, not the most affordable Mac mini)
- Mac Studio with M4 Max processor
- Mac Studio with M3 Ultra processor
RDMA support came with the macOS 26.2 update, as we wrote in the lines above. That is, all the Macs you’ll use must be running this version.
Before closing the Mac heading, let me add a small note. No, I didn’t forget to write the M5-processor MacBook Pro on the list. The first model of the M5 MacBook Pro doesn’t have a Thunderbolt 5 port.
Thunderbolt Kablo
Naturally, you need Thunderbolt 5 cables. You can examine it at this address. If your aim is to connect 4 Mac Studios to each other, you need a total of 6 Thunderbolt 5 cables.
Exo
To be able to make Macs work in a cluster structure, you’ll need a solution. An open-source project called Exo does this quite nicely. You can examine and download Exo at this address. You need to install Exo on all the Macs you’ll use in the cluster structure and select and download the LLM you’ll use from within the application. Some models are a bit too large. For example, if you want to download DeepSeek, you need to have 700GB of free space on your computer. If there’s no such free space, you don’t see those models as downloadable from within Exo either.
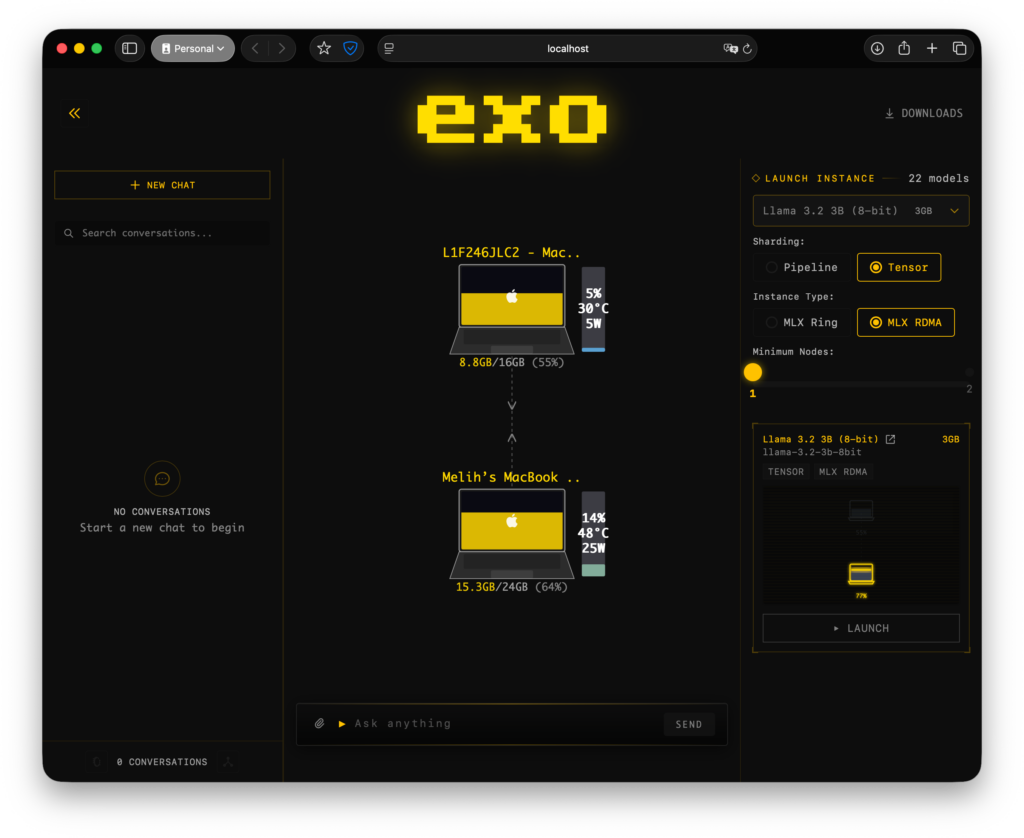
You don’t necessarily need the RDMA structure or Thunderbolt cables to use Exo for any everyday task. Just install Exo on the Macs on your network and activate it. Afterward, the queries you make from within Exo are answered using not only your own computer’s resources but the resources of the entire cluster structure. In the screenshot above, the two Macs I use appear while sharing the same task.
How Do I Activate RDMA?
You must start your Mac from macOS Recovery and open Terminal from the Utilities menu and type the following.
rdma_ctl enableWhen you type this on a device other than the computer list above, it will give an error. But when you apply it on a device that has a Thunderbolt 5 port, you see a confirmation message like RDMA enabled.
Let’s Put the Pieces Together
• You bought your Thunderbolt 5-supported Macs.
• You connected them to each other with Thunderbolt 5 cables.
• You updated all their operating systems to 26.2.
• You activated RDMA on all of them via macOS Recovery.
• You installed Exo on all the computers.
• You selected and downloaded the model you want to use from within Exo.
At this point, you no longer have anything missing to run the model you’ll use. You can get to work by asking any question you want from within Exo. But…
At this point I’ll make a small addition more. We spent all our money and time to be able to obtain higher speed. But to be able to use the power of our computers to the last drop, there’s one more missing piece of the puzzle: MLX
And What Is MLX?
MLX is an open-source library Apple developed for artificial intelligence uses. When you prefer models that use MLX, the model you use will begin to use the power of Apple Silicon more intensively. As you know, from the Apple Silicon transition onward, our Macs began to use Unified Memory. The system’s memory is used jointly by the CPU, GPU, and Neural Engine. The time losses that could occur with the transfer of the data to be processed between CPU-Memory-GPU are prevented. And the shared memory usage in the Intel days worked this way.
MLX libraries give the institutions that develop AI models the ability to use Unified Memory with all its power. End users preferring the MLX version as their LLM if there is one instead of GGUF carries the meaning of being able to benefit 100% from the power of Apple Silicon.
To activate MLX on your computer, you must first install Python or Xcode, then open Terminal and type the following.
pip install mlxIn addition to this, to also install the MLX toolkits, you must type the following command.
pip install mlx-lmTo gain additional information about MLX, you can visit this address or the project’s GitHub page.
Additional Resources
Alex Ziskind’s this YouTube video will give you a lot of information about the RDMA networking application.
Some presentations about MLX were also included at Apple’s WWDC Developer conference. You can watch the Get Started with MLX for Apple Silicon presentation by Awni Hannun, who works most actively on the MLX project.

Photo by Shubham Dhage on Unsplash
Leave a Reply